Every page, in every one of 22 scripts.
A fully parallel, multi-task document corpus: 4.4 million rendered pages and 4.3 million section crops, each carrying layout boxes, reading-order OCR ground truth, cell-level table translations and grounded question–answer pairs.
Everything below is a real sample streamed from the release, followed by the tasks it trains and how today's open models score on its companion benchmark.
Four datasets. Two to train on, two to test on.
All 22 languages in every dataset, identical schema per language. Full column reference in the specification below.
Page-level parallel corpus
Columns
Section-level degraded corpus
Columns
NayanaOCRBench Natural
Columns
NayanaOCRBench Synthetic
Columns
One source page, twenty-two renderings, one set of annotations.
Pick a document and a language. Each tile is the same page re-typeset in a different script with the layout preserved, so region IDs, bounding boxes, tables and VQA pairs line up across all 22 languages. That gives you cross-lingual pairs, script-invariant supervision and clean cross-script ablations without any alignment work.
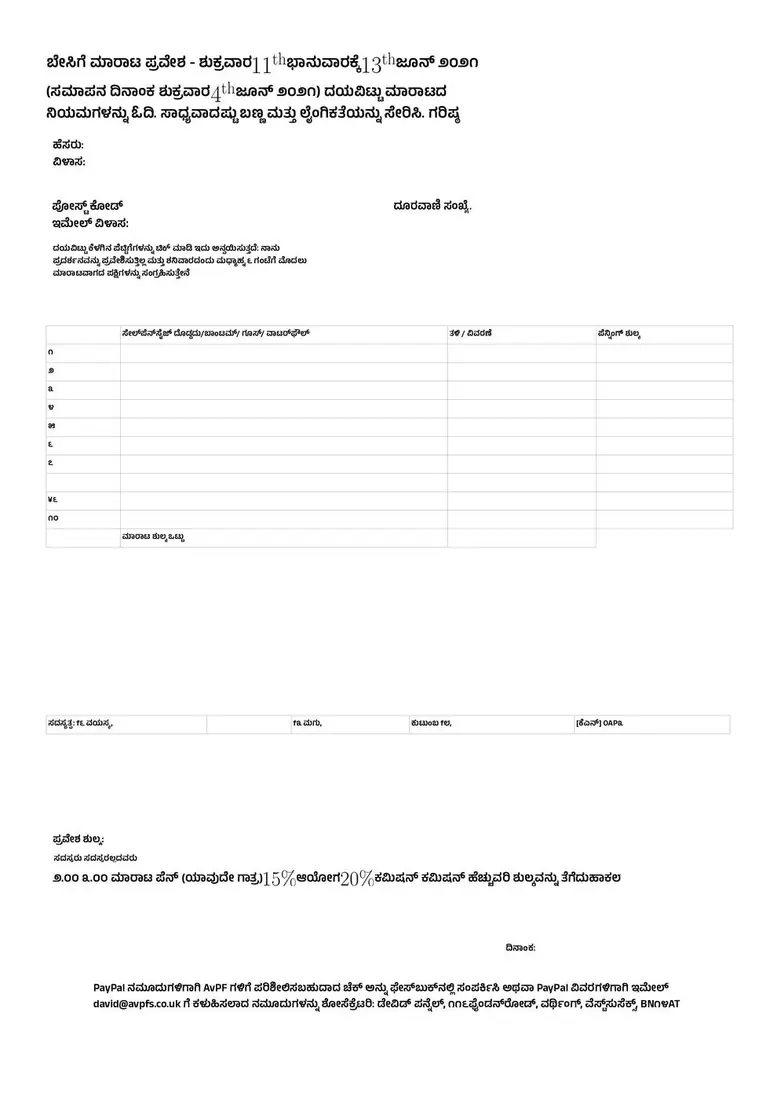
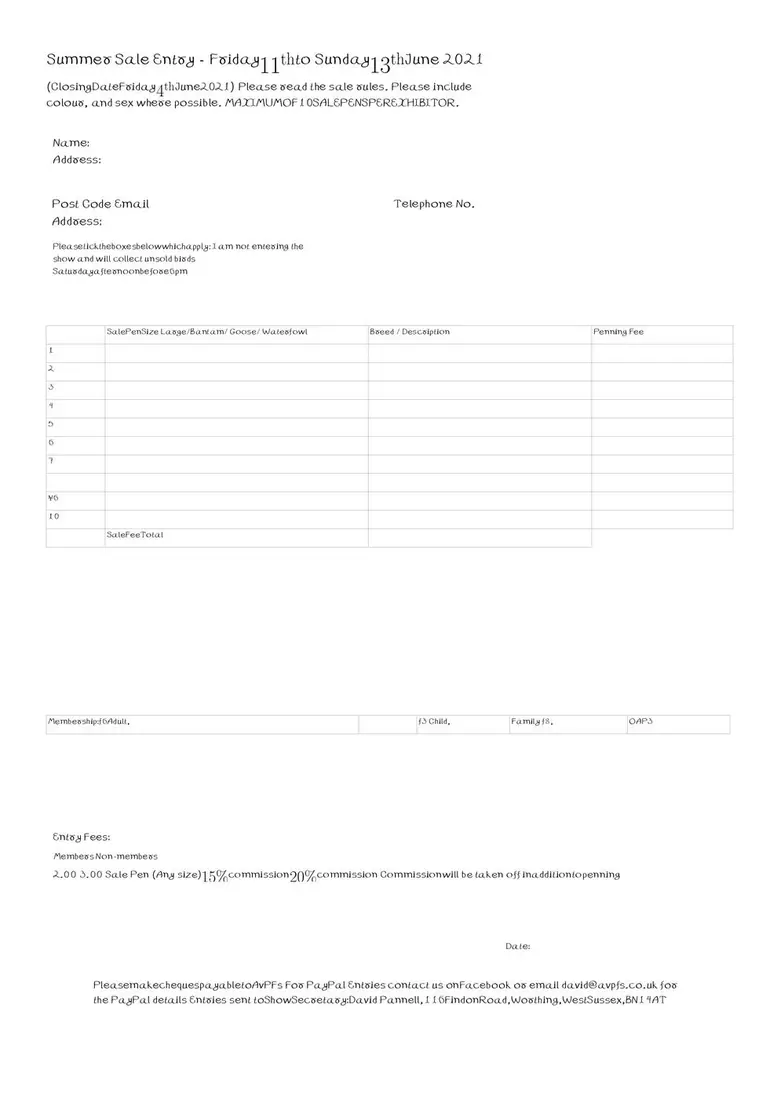
13 regions. Left is the English source text, right is what was rendered onto the Kannada page. Tables are translated cell by cell.
Six supervision signals from one row.
Every field below is present on every page-level row, in every language. Field names are the parquet columns.
Full-page OCR
Reading-order transcription of the whole page as Markdown and HTML, plus OmniDocBench JSON with per-block text, LaTeX for equations and HTML for tables.
Layout detection
Typed bounding boxes for titles, text blocks, lists, tables, figures, captions, footnotes and index entries, normalised to 1000×1000 and in native pixels.
Document translation
Region-aligned English → target text for every block, with a fit ratio recording how well the translation filled the original box.
Table structure
Tables translated cell by cell and re-rendered, with the HTML kept alongside original and rendered bounding boxes.
Document VQA
Grounded question–answer pairs per page, translated into the target language, for instruction tuning and evaluation.
Cross-lingual retrieval
The same page in 22 scripts with a shared original_id yields cross-lingual query–document pairs for free. This is how we trained NetraEmbed and ColNetraEmbed in M3DR: 0.716 NDCG@5 cross-lingual vs 0.284 for ColPali-v1.3, a 152% relative gain on the Nayana-IR benchmark derived from this corpus.
Twenty-two languages, weighted toward the scripts models get wrong.
One representative page per language, chosen for layout richness. Fonts rotate across dozens of Noto and open-licence families per script so models cannot overfit to a single typeface. Click any page to zoom with layout overlay and ground truth.
Region crops with real-world damage.
Click any crop to see the full section ground truth formatted, plus the exact degradation assets applied. Each crop is a single layout section re-rendered through one of two pipelines: Augraphy applies scanner and print artefacts (ink bleed, folds, noise, lighting), Blender wraps the page on a 3D surface with perspective, shadow and paper texture. Indic languages and English carry ~249K crops each; other languages 120K–160K.
Two held-out test sets, one of them human-verified.
NayanaOCRBench Natural is 10.5K real document pages (scans, PDFs, photographs) across all 22 languages whose layout and text were machine-proposed and then corrected by human annotators. NayanaOCRBench Synthetic is a 16.9K-page held-out slice of the 2026 pipeline. Both ship in OmniDocBench format so existing evaluation tooling works unchanged. Both are delivered with the corpus.
Natural · human-verified
रजिस्ट्री सं. डी.एल.-33002/99

भारत सरकार
GOVERNMENT OF INDIA

2 : '

REGISTERED No. D.L.—33002/99

2u4

<!-- Image (151, 72, 819, 205) -->

असाधारण
EXTRAORDINARY
प्राधिकार से प्रकाशित
PUBLISHED BY AUTHORITY

सं. 188] दिल्ली, बृहस्पतिवार, नवम्बर 1, 2007/कार्तिक 10, 1929 [ रा.रा.रा.क्षे.दि. सं. 210

No. 188] DELHI, THURSDAY, NOVEMBER 1, 2007/KARTIKA 10, 1929 [N.C.T.D. No. 210

भाग — IV

PART-IV

राष्ट्रीय राजधानी राज्य क्षेत्र, दिल्ली सरकार

GOVERNMENT OF THE NATIONAL CAPITAL TERRITORY OF DELHI
# दीनदयाल उपाध्याय गोरखपुर विश्वविद्यालय, गोरखपुर

पत्रांक : 5803/प0सा0/2019

दिनांक 31-01-2019

# अधिसूचना

एतद्वारा समस्त सम्बंधित को सूचित किया जाता है कि एम0बी0बी0एस0 फाईनल प्रोफेशनल (पार्ट-II) बैच -2014 की मुख्य परीक्षा फरवरी / मार्च-2019 केन्द्र- बी0आर0डी0 मेडिकल कालेज, गोरखपुर केन्द्र पर निम्न कार्यक्रम के अनुसार सम्पन्न होंगी।

# एम0बी0बी0एस0 फाईनल प्रोफेशनल (पार्ट-II) बैच -2014 की मुख्य परीक्षा फरवरी/मार्च-2019

समय- प्रातः 10:00 बजे से अपराह्न 01:00 बजे तक

<!-- Table (380, 214, 931, 4
ಅಂತರಂಗ, ಜುಲಾಯಿ ೧೭, ೧೯೩೮ ಬೇಕು. ಅಮ್ಮಾ! ಹೇಗಾದರೂ ‘ನಮ್ಮಪ್ಪ’ನನ್ನು ನಾವು ಕೊಂದು ಹಾಕಬೇಡವೇ? ಇಷ್ಟರತನಕ ಸಮತಾವಾದಿ ಪಕ್ಷವು 'ಕಾಂಗ್ರೆಸ್' ಸಮತಾವಾದಿ ಪಕ್ಷವಾಗಿತ್ತು. ಆದರೆ ಹೊಸತೊಂ ದು ಪಕ್ಷವು ಕಾಂಗ್ರೆಸಿನ ಒಳಗಿದ್ದು ಹೋರಾಡುವುದಂತೆ. 'ಕಾಂಗ್ರೆಸ್ ಸಮತಾವಾದಿ ಪಕ್ಷ'ವು ತನ್ನ ಹೆಸರಿನಿಂದ 'ಕಾಂಗ್ರೆಸ್' ಎಂಬು ದನ್ನು ಬಿಟ್ಟುಬಿಡುವುದಂತೆ. ಕಾಂ ಗ್ರೆಸಿನೊಳಗಣ ಈ ತೀವ್ರಗಾಮಿ ಪಕ್ಷವು ಪಾರ್ಲಿಮೆಂಟರೀ ಮನೋ ವೃತ್ತಿಯವರೊಡನೆ ಹೋರಾಡುವು ದಂತೆ. ಶ್ರೀಗಳಾದ ಭೂಲಾಭಾಯ್, ಸತ್ಯಮೂರ್ತಿಯವರು ಏನು ಮಾಡ ಲಿದ್ದಾರೆಂಬುದು ಇನ್ನೂ ತಿಳಿದು ಬಂದಿಲ್ಲ. ಮುತ್ತಣ್ಣ ಬಸವತ ಸಂಪರ್ಕ ನನ್ನ ಕಾಂಗ್ರೆಸ್ ನಿಲ್ಲಿಸುವವರೆಗೂ ಸಂಯ
<!-- Image (778, 14, 856, 68) -->

<!-- Image (111, 16, 204, 78) -->

# ಯುವ ಸಬಲೀಕರಣ ಮತ್ತು ಕ್ರೀಡಾ ಇಲಾಖೆ

<!-- Image (143, 99, 334, 274) -->

ನಿಮ್ಮ ಸಹಾಯಕ್ಕೆ ಯುವ
ಸಹಾಯವಾಣಿ

<!-- Image (148, 297, 259, 369) -->

ಯಾವುದೋ ಸಮಸ್ಯೆಯಿಂದ ನೀವು ಕಂಗಟ್ಟಿದ್ದೀರಾ?

<!-- Image (158, 378, 261, 445) -->

ದಾರಿ ಕಾಣದೆ ನೀವು ಹತಾಶರಾಗಿದ್ದೀರಾ?

<!-- Image (156, 455, 257, 523) -->

ಮಾರ್ಗದರ್ಶನದ ಅಗತ್ಯವಿದೆಯೇ?

<!-- Image (161, 529, 258, 598) -->

ನೀವು ಕ್ರೀಡೆಗಳಲ್ಲಿ ನೋಂದಾಯಿಸಬೇಕೆ?

<!-- Image (160, 608, 256, 676) -->

ವೃತ್ತಿ ಮಾರ್ಗದರ್
<!-- Image (345, 118, 475, 292) -->

<!-- Image (525, 117, 674, 290) -->

<!-- Image (196, 331, 239, 370) -->

உரு 3.22 ▲ ஏறும் தண்டுகளை கொண்ட தாவரங்கள்

மரமஞ்சள்

போஞ்சி

• அட்டவணை 3.5 ஐப் பிரதிசெய்து தாவரத் தண்டுகளின் வேறு தொழில்கள் தொடர்பாக முடியுமான அளவு உதாரணங்களைக் கொண்டு பூரணப்படுத்துங்கள்.

● அட்டவணை 3.5 ஐப் பிரதிசெய்து தாவரத் தண்டுகளின் வேறு
தொழில்கள் தொடர்பாக முடியுமான அளவு உதாரணங்களைக் கொண்டு
பூரணப்படுத்துங்கள்.

# ஒப்படை 3.2

<!-- Table (202, 457, 838, 575) -->

| புதிய தாவரத்தைத் தோ
<!-- Image (160, 146, 224, 195) -->

# 4

# சடப்பொருளின்

<!-- Image (508, 153, 570, 199) -->

<!-- Image (577, 132, 808, 217) -->

# இயல்புகள்

# 4.1 சடப்பொருள்களின் தொடர்ச்சியற்ற தன்மை

<!-- Image (163, 360, 205, 396) -->

* கீழே தரப்பட்டுள்ளவற்றை சடப்பொருள்கள், சக்தி (சடப்பொருள் அல்லாதவை) என வகைப்படுத்தவும்.
வலி, நீர், போத்தல், பந்து, ஒளி, மின்குமிழ், ஒலி, மேசை, கதிரை, மின், வெப்பம், காந்தம்

● கீழே தரப்பட்டுள்ளவற்றை சடப்பொருள்கள், சக்தி (சடப்பொருள் அல்லாதவை) என வகைப்படுத்தவும்.
வளி, நீர், போ
Academic Journal of Pediatrics & Neonatology

The mean age of studied neonates was 11.6 days (Standard Deviation SD +7.6), range 1-30 days. The HRR checklist highlighted that the risk factors for hearing loss was present in 25% of neonates ‘n=125’. More than one risk factor was seen in 14% ‘n=70’ while in the remaining neonates ‘11%; n=55’ single factor was met. Table 1 showed the common risk factors seen in

<!-- Table (508, 103, 930, 318) -->

| 0 | 726 | 96.8% | 24 | 3.2% | 750 |
| --- | ---
18.31

INDUSTRIAL AUTOMATION & PROCESS CONTROL CABLES

# Belden Infinity® Flexible Automation Cable
Overview and Application Guide

Belden Infinity is a complete line of control, data, video, and power cables specifically designed to handle the rigorous speeds and near-constant motion encountered in automated equipment such as robots, pick and place machines, automatic handling systems, multi-axis machine tools, and conveyor systems.

When the application demands highly flexible cables offering
HANDELSZEITUNG | Nr. 9 | 28. Februar 2013

3

<!-- Image (0, 79, 565, 496) -->

Das im Dezember eröffnete Lager
von Zalando in Erfurt: Auch von hier
gehen Waren in die Schweiz.

die Quote auf über 60 Prozent steigt, wird es aber schon schwierig.» Jeder Versandhändler muss aber
Retouren möglichst vermeiden. Das tut Zalando
auch. Aus dem ursprünglichen Werbeslogan «Schrei
vor Glück oder schicks zurück» lassen die Berliner
den zweiten Teil nun weg. Dennoch bleibt die hür-
denlose Retourenabwicklung
BAUSCHÄDEN

don herzustellen. Für das Haus wurde
darauf aufbauend vom Fertighausanbie-
ter eine Kunststoffbahn-Abdichtung un-
ter der Bodenplatte ›geplant‹. Der Unter-
nehmer hat dementsprechend eine über
die gesamte Grundfläche des Bauwerkes
reichende 1,5 mm dicke EPDM-Bahn vor-
fertigten und verlegen lassen. Die EPDM-
Bahn besitzt die Zulassung eines europä-
ischen Prüfinstitutes (Tschechien) auf
Dichtheit gegenüber Radongas.

# Baufehler

Die Planung und Ausführung von Bauar-
beiten hat gemäß
镇江恒华彩印包装有限责任公司拟整合重组涉及的股东全部权益价值项目资产评估报告·附件

<!-- Table (132, 99, 864, 118) -->

|  | 合计 | 500.00 | 100.00% | 500.00 | 100.00% |
| --- | --- | --- | --- | --- | --- |

2008 年 10 月,根据恒华彩印公司股东会决议,同意股东镇江市嘉年华节日
用品制造有限公司将其持有的所有股权转让给蔡沛均。完成股权转让后的股权结
构如下:

金额单位:人民币万元

<!-- Table (132, 233, 865, 324) -->

| 序号 | 股东名称 | 注册资本 | 实收资本 |
| --- | --- | --- | --- |
| 金额 | 比例 | 金额 | 比例 |
| 1 | 江苏恒顺醋业股份有限公司 | 300.00 | 60.00% | 300.00 | 60.00% |
| 2 | 蔡沛均 | 200.00 | 40.00% | 200.00 | 40.00% |
|  | 合计 | 500.00 | 100.
镇江恒华彩印包装有限责任公司拟整合重组涉及的股东全部权益价值项目资产评估报告·附件

和技术除外);普通货物运输。(依法须经批准的项目,经相关部门批准后方可
开展经营活动)

# (二)被评估单位概况

# 1、基本情况

公司名称:镇江恒华彩印包装有限责任公司(以下简称:“恒华彩印公司”)

法定住所:镇江市丹徒新城恒园路 3 号

经营场所:镇江市丹徒新城恒园路3号

法定代表人:李国权

注册资本: 500.00 万元人民币

经营范围:包装装潢印刷品排版、制版、印刷、装订;其他印刷品印刷;纸
包装物品、纸箱的制造;印刷器材及零配件、纸张的销售;设计、制作、代理、
发布各类广告;数码照相扩印服务;道路普通货物运输(危险品除外);自营和
代理各类商品及技术的进出口业务(国家限定企业经营或禁止进出口的商品及技
术除外)。(依法须经批准的项目,经相关部门批准后方可开展经营活动)

# 2、公司股东及持股比例、股权变更情况及主要的长期股权投资情况

# ①公司股东及持股比例和股权变更情况

恒华彩印公司于 1998 年 12 月 9 日成立, 由江苏恒顺集团公司和镇江市嘉年
华节日用品制
推奨ランド寸法

チップ形 (導電性高分子ハイブリッド)

アルミニウム電解コンデンサ

ELNA

# ■推奨ランド寸法

(縦形タイプ)

● 標準タイプ

<!-- Image (179, 156, 268, 288) -->

(単位:mm)

<!-- Table (98, 306, 443, 416) -->

| 外形サイズφD×L | ランド寸法 | クリームはんだ厚 |
| --- | --- | --- |
| X | Y | W |
| 5×5.8 | 1.6 | 3.0 | 1.4 | 0.15 |
| 6.3×5.8, 7.7 | 1.6 | 3.6 | 1.9 | 0.15 |
| 8×10 | 2.5 | 3.5 | 3.0 | 0.15 |
| 10×10, 12.5 | 2.5 | 4.0 | 4.0 | 0.15 |
| 12.5×13.5 | 3.2 | 6.0 | 4.0 | 0.15 |

# ● 耐振動タイプ

HT1, HTK, HTL, HTX, HTQ, HTY シリーズ

VTZ, VTD, VTT, VTV, VTX, VMD, V
<!-- Table (70, 66, 927, 178) -->

| 自分を守る! | ▶初動体制の構築 | 社員等に対する教育・啓発・訓練を行う |
| --- | --- | --- |
| 003 | 自ら考えて行動出来る人を育成する 72時間サバイバル教育 | 取組主体 |

国土強靱化

・子どもたちが、サバイバルマスタープログラム®を通じて、災害時に自ら考えて行動し、人を助けることがで
きるような人材を増やす。

# 1 取組の特徴(はじめたきっかけ、狙い、効果、工夫した点、苦労した点)

災害発生後 72 時間。生き抜く力を、子供たちに。

・一般社団法人 72時間サバイバル教育協会は、体験学習を通じて、災害時に自助・共助が行えるようになるための減災
教育を行う団体である。東日本大震災のボランティア活動を通じ、大阪のアウトドア会社、キャンプ団体及びキャリア
教育団体が集まり、活動を開始。2013 年に法人化した。

・同法人は、サバイバルマスター®というプログラムを、全国の野外教育施設
や公園などで、協会公認ディレクターが主導のもと、年に数回ずつ定期的に
実施する。
وبعد الإطلاع على بقية مظروفات الملف وعلى ما يفيد استيفاء إجراءات التحقيق في

الدعوى.

وبعد الاطلاع على القانون الأساسي عدد 22 لسنة 2016 المؤرخ في 24 مارس

2016 والمتعلق بالحق في النفاذ إلى المعلومة وخاصة الفصل 38 منه.

# قَرَّرَتْ الهيئةُ ما يلي:

# بخصوص ضَمِّ القضيَّتَيْنِ:

حَيْثُ تَثْبُتُ بِالرُّجُوعِ إِلَى عَرَائِضِ الدَّعَاوَى عَدَدِ 378 وَ 379 أَنَّهَا مُوَجَّهَةٌ ضِدَّ نَفْسِ

الهيكل العمومي وهو جامعة المنستير في شخص ممثلها القانوني ، وأنها تهدف إلى البت

في موضوع مشترك بينها مُتَّصِل بح
وأخيرا فإن الفقرات التي تنتمي إلى بعد التقييم والتي حصلت على أعلى

متوسطات كانت تتمثل باستخدام التقويم لقياس تحقق الأهداف التعليمية ، وتعديل ل

تلك الأهداف على ضوء نتائج التقويم .

وللإجابة عن سؤال الدراسة الثاني والمتعلق بالفروق في مستوى إتقان

مهارات التدريس بين كل من المعلمين الذكور والإناث، فقد تم اختبار الفروق على

الدرجة الكلية والأبعاد الفرعية بإستخدام إختبار (ت) للعينات المستقلة. ومما تجدر

الإشارة إليه هنا ان قلة عدد الحالات في بعض الخلايا عندما تم توزيع أفراد العينة

إلى متغيرات الدراس
Synthetic · held-out · 21 languages reported; English ground truth is being revised and is excluded from this preview
# आइसोचेक 37T प्रणाली

रूपांतरण और नवीनीकरण के लिए सीधे जॉयिस्ट तक (प्रत्यक्ष निश्चित छत का उपयोग करके)

# उत्पाद डेटा

<!-- Table (85, 134, 511, 198) -->

प्रदर्शन (नीचे चित्रित निर्माण पर)

<!-- Table (84, 255, 511, 290) -->

# विवरण

Isocheck37T सिस्टम को ध्वनि संचरण को कम करने और पारंपरिक जॉयस्टेड लकड़ी के फर्श और कंक्रीट फर्श को थर्मल रूप से बढ़ाने के लिए डिज़ाइन किया गया है।

जब एक संपूर्ण पार्टी फ़्लोर के हिस्से के रूप में स्थापित किया जाता है, तो यह सिस्टम पारंपरिक लकड़ी के बने फ़्लोर को
# ಐಸೊಚೆಕ್ ೩೭T ವ್ಯವಸ್ಥೆ ಪರಿವರ್ತನೆ ಮತ್ತು ನವೀಕರಣಕ್ಕಾಗಿ ಜೋಯಿಸ್ಟ್ಗಳಿಗೆ ನೇರವಾಗಿ (ನೇರ ಸ್ಥಿರ ಸೀಲಿಂಗ್ ಬಳಸಿ) # ಉತ್ಪನ್ನ ಡೇಟಾ <!-- Table (85, 134, 511, 198) --> ಕಾರ್ಯಕ್ಷಮತೆ (ಕೆಳಗೆ ವಿವರಿಸಿದ ನಿರ್ಮಾಣದ ಮೇಲೆ) <!-- Table (84, 255, 511, 290) --> # ವಿವರಣೆ ಐಸೊಚೆಕ್ ೩೭ ಟಿಸಿಸ್ಟಮ್ ಅನ್ನು ಧ್ವನಿ ಪ್ರಸರಣವನ್ನು ಕಡಿಮೆ ಮಾಡಲು ವಿನ್ಯಾಸಗೊಳಿಸಲಾಗಿದೆ ಮತ್ತು ಸಾಂಪ್ರದಾಯಿಕ ಜೋಯಿಸ್ಟ್ ಮರದ ಮಹಡಿಗಳು ಮತ್ತು ಕಾಂಕ್ರೀಟ್ ಮಹಡಿಗಳನ್ನು ಉಷ್ಣವಾಗಿ ವರ್ಧಿಸುತ್ತದೆ. ಸಂಪೂರ್ಣ ಪಾರ್ಟಿ ಫ್ಲೋರ್ನ ಭಾಗವಾಗಿ ಸ್ಥಾಪಿಸಿದಾಗ, ಈ ವ್ಯವಸ್ಥೆಯು ADE೨೦೦೩ (ತಿದ್ದುಪಡಿ ೨೦೦೪) ನ ಧ್ವನಿ
# Das isocheck 37T-System

Direkt an Balken für Umbau und Sanierung (unter Verwendung einer direkten festen Decke)

# PRODUKTDATEN

<!-- Table (85, 134, 511, 211) -->

LEISTUNG (auf der unten dargestellten Konstruktion)

<!-- Table (84, 255, 511, 290) -->

# BESCHREIBUNG

Das Isocheck37T-System ist darauf ausgelegt, die Schallübertragung zu reduzieren und herkömmliche Holzbalkenböden und Betonböden thermisch zu verbessern.

Bei der Installation als Teil eines kompletten Partybodens ermöglicht di
# ポリパネル

<!-- Image (77, 89, 926, 333) -->

説明 - 構造 - 仕様

DB および DBL フィルターは、ワイヤーフレーム上の 2 層の高密度合成繊維で作られています。

まず、乾燥層が大粒および中粒径の粒子を侵入時に捕捉します。その後、粘着性の層が出口で最小の粒子を保持します。このフィルター パネルは、さまざまな動作条件で優れた空気品質を提供します。さらに、これらのパネルは湿気に耐えるように設計されています。フレームに沿った空気のバイパスを防ぐために、2 層のメディアが全周に縫い付けられています。

DB および DBL フィルターは、1 インチおよび 2 インチのスロットに簡単に取り付けられます。連結されているため、締結装置は必要ありません。

<!-- Table (98, 628, 428, 676) -->

ASHRAE 52-76 試験法 ot 300 fpm に基づいた試験結果

193 Rang de l'eglise St-Liguori (ケベック) J0K2X0 電話: (450) 754-4222 ファックス: (
No open model reads all 22 scripts.
We ran 13 open vision-language and OCR models zero-shot on both benchmarks (May–June 2026, 470 model×language runs). Latin, Cyrillic and CJK are largely solved. Kannada, Odia, Malayalam and Telugu are not: the strongest general-purpose family scores above 90% on European scripts and under 20% on those four, at every model size. Cells show character accuracy; grey cells are languages the model does not claim.
Three peer-reviewed steps from OCR to retrieval.
The 2026 corpus is the third iteration of a published pipeline. Each paper below is built on, and evaluated with, the previous release; the methods, failure modes and quality controls are documented and citable.
Nayana OCR: A Scalable Framework for Document OCR in Low-Resource Languages
Kolavi, Samarth, Jain. Introduced the synthetic re-typesetting approach: take layout-annotated English pages, translate region by region, and render in the target script with real fonts. Showed that models fine-tuned on the synthetic pages transfer to real Kannada, Hindi and other Indic documents. This is the generation engine behind every Nayana release.
Nayana: A Foundation for Document-Centric VLMs via Multi-Task, Multimodal and Multilingual Data Synthesis
Kolavi, Jain. Extended the pipeline from OCR to the full task set on this page: layout detection, translation, table structure and grounded VQA, all generated together so every page carries every label. Produced the 1M-page NayanaOCR Corpus 2025 that is public today; the 2026 corpus is its 5× successor.
M3DR: Towards Universal Multilingual Multimodal Document Retrieval
Kolavi, Jain. The parallel-corpus payoff. Using the same page in 22 scripts as free cross-lingual positives, trained NetraEmbed (single-vector, Gemma 3 4B backbone, Matryoshka 768/1536/2560) and ColNetraEmbed (ColBERT-style late interaction) and released the Nayana-IR benchmark. NetraEmbed: 0.716 NDCG@5 cross-lingual vs 0.284 for ColPali-v1.3 (+152%), +80% monolingual, consistent across Latin, Devanagari, Dravidian, CJK and Arabic scripts.
BibTeX for all three papers
@inproceedings{kolavi2025nayanaocr,
  title     = {Nayana {OCR}: A Scalable Framework for Document {OCR} in Low-Resource Languages},
  author    = {Kolavi, Adithya S. and Samarth, P. and Jain, Vyoman},
  booktitle = {Proceedings of the 1st Workshop on Language Models for Underserved Communities (LM4UC)},
  year      = {2025}, pages = {86--103},
  url       = {https://aclanthology.org/2025.lm4uc-1.11/}
}

@inproceedings{kolavi2025nayana,
  title     = {Nayana: A Foundation for Document-Centric Vision-Language Models via Multi-Task, Multimodal, and Multilingual Data Synthesis},
  author    = {Kolavi, Adithya S. and Jain, Vyoman},
  booktitle = {Proceedings of the IEEE/CVF International Conference on Computer Vision Workshops (ICCVW) -- CV4DC},
  year      = {2025}, pages = {1678--1687}
}

@misc{kolavi2025m3dr,
  title         = {{M3DR}: Towards Universal Multilingual Multimodal Document Retrieval},
  author        = {Kolavi, Adithya S. and Jain, Vyoman},
  year          = {2025}, eprint = {2512.03514}, archivePrefix = {arXiv}, primaryClass = {cs.IR},
  url           = {https://arxiv.org/abs/2512.03514}
}What you receive.
| Release | Contents |
|---|---|
| Page-level corpus | 22 parquet configs, ~200K rows each, 4.4M rows total, ~1.5 TB. 14 columns per row (image + 13 annotation fields). Most pages 1993×2579 or 2741×1940 px. |
| Section-level corpus | 22 parquet configs, 120K–250K rows each, 4.3M rows total, ~4.7 TB. Image, section type, section text, renderer, and the list of Augraphy / Blender assets applied. |
| Benchmarks | NayanaOCRBench Natural (10.5K pages, human-verified) and Synthetic (16.9K pages), both in OmniDocBench format, delivered with the corpus. |
| Evaluation harness | Scripts and raw traces for the 13-model zero-shot study, so your own models can be scored the same way. |
| Format | Parquet (streamable with datasets); WebDataset TAR shards on request. |
| Provenance | Source pages from open document collections (Docmatix / PDFA lineage), translated and re-typeset by the VIVID pipeline described in our LM4UC 2025 and ICCVW 2025 papers. Fonts are Noto and other open-licence families. |
| Availability | Private release, licensed per agreement. Evaluation access, per-language subsets and delivery options are arranged directly. Write to contact@cognitivelab.in. |
| Column | Type | Meaning |
|---|---|---|
| image | Image | Rendered page |
| original_id | string | Source page id, identical across all 22 configs |
| font_used | string | Font file for this rendering |
| page_size | [int,int] | Layout coordinate space |
| rendered_layout | list | Per region: type, coords, original + translated text, fit_ratio |
| translated_tables | list | Translated tables as HTML with original/rendered bbox |
| vqa_translated | list | Q/A pairs in target language |
| omnidocbench* | struct | OmniDocBench JSON (original, translated, normalised) |
| html_norm1000 · md_norm1000 | string | Full-page GT in reading order |
| layout_norm1000 | list | type + bbox on a 1000×1000 grid |
| layout_content_norm1000 | list | type + bbox + text |
Per-language counts
| Language | Code | Script | Page-level rows | Section-level rows | Bench · Natural | Bench · Synthetic |
|---|---|---|---|---|---|---|
| Hindi Indic | hi | Devanagari | 200.3K | 249.3K | 500 | ~770 |
| Bengali Indic | bn | Bengali | 200.6K | 249.0K | 467 | ~770 |
| Marathi Indic | mr | Devanagari | 200.4K | 248.9K | 515 | ~770 |
| Gujarati Indic | gu | Gujarati | 200.5K | 249.7K | 445 | ~770 |
| Punjabi Indic | pa | Gurmukhi | 200.7K | 249.9K | 463 | ~770 |
| Odia Indic | or | Odia | 200.7K | 249.1K | 301 | ~770 |
| Kannada Indic | kn | Kannada | 200.0K | 250.0K | 500 | ~770 |
| Tamil Indic | ta | Tamil | 200.7K | 249.9K | 504 | ~770 |
| Telugu Indic | te | Telugu | 200.7K | 249.9K | 461 | ~770 |
| Malayalam Indic | ml | Malayalam | 200.7K | 249.7K | 492 | ~770 |
| Sanskrit Indic | sa | Devanagari | 200.6K | 249.6K | 425 | ~770 |
| English European | en | Latin | 200.7K | 249.3K | 502 | ~770 |
| German European | de | Latin | 200.7K | 159.3K | 496 | ~770 |
| French European | fr | Latin | 200.6K | 149.8K | 504 | ~770 |
| Spanish European | es | Latin | 200.7K | 120.0K | 500 | ~770 |
| Italian European | it | Latin | 200.7K | 120.0K | 494 | ~770 |
| Russian European | ru | Cyrillic | 200.7K | 120.0K | 523 | ~770 |
| Chinese East Asian | zh | Han | 200.7K | 150.0K | 526 | ~770 |
| Japanese East Asian | ja | Kana + Kanji | 200.7K | 120.0K | 502 | ~770 |
| Korean East Asian | ko | Hangul | 200.7K | 150.0K | 454 | ~770 |
| Arabic Semitic | ar | Arabic | 200.7K | 120.0K | 452 | ~770 |
| Thai South-East Asian | th | Thai | 200.7K | 120.0K | 507 | ~770 |